Reading Big Five Papers: Claims, Design, Samples, Measures, Results, and Limits
Read beyond a Big Five paper’s headline. A six-part guide helps you identify the claim, design, sample, measures, estimates and limits without turning group findings into a personal verdict.
Reading Big Five Papers: Claims, Design, Samples, Measures, Results, and Limits
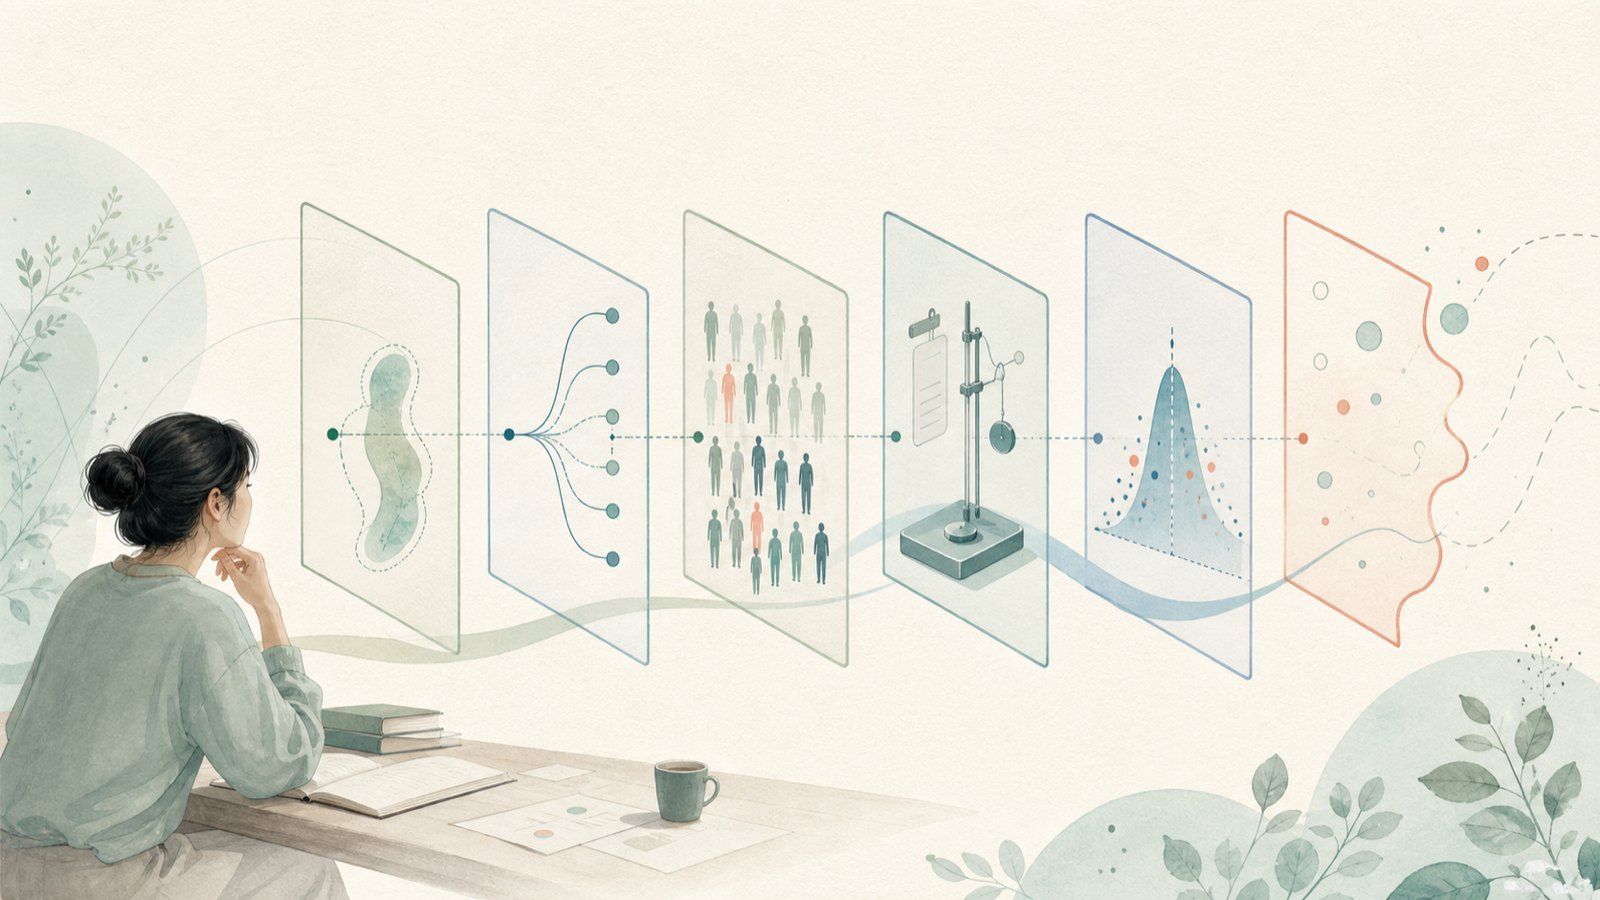
When reading a Big Five personality paper, two things can cause difficulty: the abundance of terminology and conclusions that seem to speak directly about you. A paper, however, is primarily a research record concerning particular materials, participants, and analyses, rather than a judgment about an individual reader. Instead of first asking “Is this about me?”, ask in sequence:What exactly do the authors claim? What design did they use, whom did they study, how did they measure, what results did they obtain, and where must generalization stop?
These six questions will not grade the paper for you or turn reading into a statistics exam. They turn a striking conclusion back into a limited statement that can be checked. This article does not judge your personality, ability, career, or future from research, or turn general studies into proof of FermatMind’s instruments or results, or product comparisons. Some version and scoring information is public
;
a complete item key and product-specific validation, prediction, and matching evidence are not established by those explanations.
Start with the Claim: Titles Often Say More Than the Paper Can Support
A paper’s title might say “Extraversion relates to an outcome,” “The Big Five changes with age,” or “A scale performs inconsistently.” These statements provide an entry point, not necessarily the full claim the authors can ultimately support. Return to the abstract, research questions, and discussion to identify what was actually compared, the outcome variable, and how far inference goes. Divide the claim into five blanks: who was studied, which measure represented the Big Five, what it was compared with, what result was observed, and whether the authors mean description, association, prediction, change, or causation.
For example, “Conscientiousness scores relate to a self-reported behavior in one sample” is initially an association. It does not automatically establish that conscientiousness caused the behavior or that everyone behaves this way, and cannot become “A particular career suits you” or “You will definitely perform this way.” Similarly, “An instrument showed a particular structure in one study” initially records measurement findings for that instrument, version, sample, and analysis, rather than delivering a verdict on the entire Big Five framework or every assessment page.
Rephrase the most important sentence as: “Under these conditions, researchers obtained an estimate for this limited question.” If you still cannot identify “these conditions” or “this limited question,” do not fill the gaps with news headlines, memorable abstract sentences, or secondhand interpretations. Retain Unknown where information is missing.
Examine the Design: What Comparisons and Time Order Were Arranged?
The design section does not establish whether research is “advanced.” It explains how researchers obtained and compared data, and what that arrangement can initially answer. Cross-sectional studies collect data at one time and can describe distributions or co-occurrence at that time. They cannot alone establish which variable came first or exclude all alternative explanations. Longitudinal studies track data from the same or related cohorts at multiple times, adding temporal information while still requiring attention to intervals, repeated measures, attrition, and unmeasured factors. Experiments test specific questions through explicit manipulations and comparisons, but their tasks, settings, and participants still limit their scope.
Other papers primarily develop or evaluate instruments, discussing items, dimensions, scoring, or different versions. They help explain “What exactly did the researchers measure?”, but usually do not study treatment, hiring, career outcomes, or life choices. Do not treat a paper with many models, control variables, or charts as the final answer to every real-world question.
Write three questions in the margin: Were participants randomly assigned to conditions? Were data collected once or repeatedly? Do the authors’ conclusions go beyond what this arrangement directly supports? This does not dismiss any design. A clear design helps readers state accurately what kind of information it provides.
A Sample Is More Than a Head Count: Identify Whom the Study Initially Applies To
Many readers look for sample size first. Numbers affect the precision of some estimates, but cannot alone establish whether a study represents your circumstances. Also check recruitment, age and language ranges, volunteer status, inclusion and exclusion criteria, data-collection timing and context, and attrition or missing data. A very large online sample and a smaller, specifically targeted nonclinical community sample may answer entirely different questions; head count alone cannot rank them.
In Big Five research, participants’ education, culture and language, administration methods, and response contexts especially deserve a place in your notes. Researchers report a group’s responses to particular questions or related data, not a “personality law” unconditionally applicable to every location, age, and person. If the paper did not study Chinese-speaking adults, your work environment, or a particular choice, do not silently add those subjects to its conclusion.
Distinguish “the sample average” from “every participant.” Average associations, changes, or differences within a group cannot explain why a particular participant is this way, replace their personal history, or predict their next step. A sample provides part of the boundaries of a claim, not permission to compress people into a conclusion.
Read Measurement Details: The Same Big Five Name Does Not Guarantee the Same Ruler
Big Five traits are research constructs. Researchers use specific items, instructions, versions, languages, scoring methods, and analysis rules to turn constructs into reportable data. “This study measured extraversion” is therefore insufficient. Ask which questionnaire or item bank was used, whether it was a full or short version, whether items were modified or removed, whether reports came from participants, acquaintances, or another source, which language, timeframe, and response scale were used, and how scores were combined.
These details are not a fault-finding game. The BFI-2 development paper, for example, describes a named hierarchical instrument and its validation studies. Research developing or evaluating a named instrument primarily supports information about that instrument within its reported scope. A shared dimension name does not automatically make results interchangeable across lengths, translations, administration methods, or scoring rules. Research across contexts likewise cautions against assuming that a familiar scale name means measurement has the same meaning in every language, educational setting, interview format, or response context.
When a paper omits version, language, or scoring information, neither judge it “definitely invalid” nor guess “It is all the same anyway.” Record that measurement comparability is Unknown here. This keeps later interpretation within what the available data permit.
Identify What Was Estimated: What Did Researchers Actually Calculate?
Results sections are often condensed into “significant findings” or “no relationship.” Both are too crude. First identify what was estimated: a correlation, mean difference, change trajectory, structural parameter, predictive model, or comparison between conditions. Then examine direction, size, intervals or other uncertainty information, agreement between charts and text, and whether key data-processing and analytical choices were reported.
Statistical significance is not synonymous with practical importance, causal truth, broad applicability, or individual predictability. Conversely, not meeting a study’s prespecified statistical threshold does not mean “There is no relationship anywhere.” It may reflect imprecise estimates, a mismatch between subjects and questions, or a need for more comparable records. You need not train yourself to reproduce the statistics, but avoid taking a single symbol or number to complete the story. Gardner and Altman’s discussion of estimation explains why a magnitude and its uncertainty say more than a significance label alone.
For Big Five papers, ask especially “What is the outcome variable?” If it is another self-report questionnaire, the conclusion initially concerns relationships between two sets of self-reported data in that sample. If it is an observation or follow-up record, check how and when it was collected. Neither type of group result directly explains an individual’s motives, value, health, or future.
Discussion and Limitations Are Not an Appendix: They Tell You Where Conclusions Stop
In the discussion, authors generally relate results to earlier research, suggest possible explanations, and describe limitations. Treat these as boundaries a claim must not silently cross: Is the sample from one source? Do data depend on self-report? Is temporal order insufficient? Are measures brief or incompletely described? Are there missing data, attrition, multiple analysis choices, or unmeasured variables? Did the study omit direct comparison of the subjects you care about?
Limitations do not necessarily make a paper worthless. Every study must delimit its question, and limitations sometimes reflect accurate descriptions of scope. Conversely, including limitations does not resolve every question. Connect each limitation to the claim: Does it affect generalization, causation, measurement interpretation, precision, or comparability with other studies?
If the paper lacks information you need, or existing data cannot support a stronger statement, leave that step as Unknown. This is closer to the research record than treating limitations as polite formalities and continuing to express certainty.
Place a Paper in the Cumulative Record, Rather Than Asking Which Side It Takes
A study is not an isolated verdict. After reading claims, design, samples, measurements, results, and limitations, ask whether comparable data exist for similar questions, instruments, and populations. Do differences represent repetition, extension, conditions, conflict, or entirely different questions? Replication, robustness, and reproducibility provide further testing opportunities, but must also be read with their materials, samples, analyses, and timing;Nosek and colleagues’ review explains their role in scientific self-correction.
“Replicated” is not a quality badge detached from details, and different results do not prove that an entire original study or field has been overturned. Systematic reviews and meta-analyses can organize studies, but you must still check comparability, the presentation of differences, and whether the synthesized conclusion answers the current question. Cumulative evidence lets the same claim undergo repeated testing under explicit conditions; it does not provide a permanent label.
Mark an unexpected conclusion as “a record to compare” rather than “a life judgment to update immediately.” This gives new research its proper place without granting a single paper extra authority.
A Fictional Exercise: Unpack “Extraversion Determines Remote-Work Performance”
Suppose a report says: “Research proves that extraversion determines remote-work performance.” Do not accept or reject the headline immediately. Return to the paper and restate the actual claim: Did researchers merely collect one extraversion self-report and one self-report of work experiences from volunteers in a particular industry? If so, the design may initially support only an association at one time in a particular sample. It has not alone proved “determines” or guaranteed applicability to other occupations, teams, cultures, or individuals.
Then examine the sample: where participants came from, the working arrangements and timing, and who did not participate or withdrew. Examine measurement: which extraversion version was used, who reported performance using which measure, and whether both variables were self-reported. Examine results: whether the estimate concerns correlation or prediction, whether uncertainty was reported, and whether alternative analyses were compared. Finally, read limitations: which generalizations the authors exclude, and whether other data are needed for testing.
After these steps, you need not give a general verdict of “good paper” or “bad paper.” A more accurate note might read: “It provides a limited association record for a particular population and particular measurements; individual remote-work choices and employment judgments do not follow.” This is the boundary research reading should retain.
A Six-Box Reading Card: Record the Information Before Deciding Whether to Continue
Use these six boxes to take notes on any Big Five paper. They are not an evidence-rating table or a requirement to do additional statistics.
Claim. What do the authors actually conclude: description, association, prediction, change, or causation?
Design. How were data arranged, and were there comparisons and temporal ordering? What can this design initially answer?
Sample. Who was studied, where did they come from, when and where were data collected, and who may not be covered?
Measurement. Which instrument, version, language, reporter, and scoring rules were used? Which details are missing?
Results. What was estimated, in which direction, with what magnitude and uncertainty? What information remains unreported or undecidable?
Limitations and cumulative record. Where does the claim stop? Which related studies, replications, or reviews merit comparison?
After the six boxes, add “What this does not imply.” For example: group associations do not establish individual causes; instrument papers do not make every scale interchangeable; one longitudinal record does not guarantee someone will change; and a statistical result cannot carry hiring, admissions, medical, legal, or financial decisions. Writing this down keeps reading within evidence rather than imagination.
FermatMind: General Papers Do Not Automatically Become Product Information
FermatMind’s public Big Five test guide describes its 90-question and 120-question versions, five domains and 30 facets, reverse scoring, aggregation, and z-score/T-score conversions. These method descriptions do not establish product validation. A percentile calculated from an assumed normal model is not an observed rank in a representative population; read the stated reference source and norm status. The full item key and product-specific research on reliability, validity, measurement error, cross-language equivalence, retesting, meaningful change, intervention effects, individual prediction, and career or relationship matching are not established by these public explanations. Their evidential support remains Unknown here.
A Big Five instrument paper, longitudinal study, cross-context measurement study, or methodological review can at most help readers understand the limited questions each addresses. They do not automatically certify or invalidate a product, or establish that a particular reader’s score is accurate, stable, comparable, predictive, or suitable for action. Separating general research from product evidence prevents transferring evidence across boundaries; it does not dismiss research’s value.
Do Not Turn Paper Reading into Diagnosis or High-Risk Decisions
This article is educational material for reading research and limited self-reflection. It does not diagnose psychological or medical conditions, judge personality as good or bad, or assess ability, hiring eligibility, admissions eligibility, career fit, relationship quality, legal responsibility, financial choices, or future outcomes. No article, personality study, review statistic, or self-test should alone carry a decision that substantially affects your own or others’ interests.
If reading research brings ongoing distress or health or safety concerns, research headlines and personality labels should not replace support and judgment in your real situation. Research helps us ask clearer questions, identify boundaries, and find appropriate follow-up material. It does not decide who someone is or what they should receive.
Frequently Asked Questions
Can a Big Five Paper’s Abstract Be Treated Directly as Its Conclusion?
An abstract helps locate the question, but should not replace reading samples, design, measurement, results, and limitations. Especially when it uses words such as “prediction,” “change,” or “influence,” return to methods and results to establish their specific meaning in that paper.
Does a Large Sample Represent Me?
Not automatically. Sample size is only one piece of information. Recruitment, language, context, measurement, timing, and research questions also determine whom a group-level record initially applies to. Group results do not directly answer individual causes or futures.
Does a Significant Result Show That Personality Caused Something?
Significance alone cannot establish that. Examine the actual design, comparisons, temporal order, alternative explanations, and uncertainty. A statistical label does not automatically provide causal conclusions or individual predictions.
If a Paper Lists Limitations, Is It Not Worth Reading?
No. Limitations tell readers where a claim stops. Ask instead whether a limitation affects generalization, measurement interpretation, causation, precision, or comparability with other studies.
Can One Big Five Paper Prove That FermatMind Results Are Accurate or Predict the Future?
No. General research supports only its own instruments, samples, designs, and analytical scope. FermatMind-specific psychometrics, effects, predictions, and matching details are all Unknown in this article.
Sources and Scope
These sources support the measurement, estimation, and replication questions in this guide. They do not validate FermatMind or establish an individual’s personality, work performance, or future.
After reading a paper, the most valuable outcome need not be a quick judgment. If you can explain clearly what it studied, what it did not study, and what needs checking next, you have already read one layer beyond the headline.
How to Read a Big Five Research Paper | FermatMind