Quick answer: check what Big Five scores are based on, then consider the context
Big Five results usually describe five continuous dimensions: openness, conscientiousness, extraversion, agreeableness, and negative emotionality. First check the instrument, score type, and basis for comparison. Then turn high and low scores into questions about behavior in specific situations, while also looking for counterexamples. Results can support self-reflection, but this article does not establish their suitability for assessing ability, diagnosis, applicant screening or individual prediction.
The Big Five Hub provides a complete overview of the five-dimension model; this page focuses only on reading results, using them, and their limits.
A striking number may still be missing key information
Consider a fictional example: Xiaolin reads “Extraversion 42” while wondering why she rarely volunteers to speak in project meetings. The report does not explain what 42 means or whom it compares her with. She wonders whether to send it to her supervisor.
Two reports that both say “42” do not necessarily mean the same thing. The number may be a total of item scores, a transformed score, or a position relative to a comparison group. Without a scale and reference, it cannot establish that “I am worse than other people,” “I am not suited to management,” or “I must change.”
Big Five research offers a broad structural framework for understanding personality differences, rather than an identity card that stamps a label on an individual. Goldberg (1990) reported the generality of the five-factor structure in factor-analytic samples using trait terms. This helps explain why many tools use Big Five language; it does not mean every online report measures the same content, or that a report can answer questions about work, relationships, or life choices for someone.
If two reports give different results, there is no need to argue immediately about which one is “more accurate.” More useful questions are whether they use the same tool or version, whether scores are presented in the same way, whether they share a basis for comparison, and whether the circumstances of answering were similar. When information is insufficient, the appropriate label is “needs verification,” rather than immediately defining yourself by a number.
Before the test: turn anxiety into an observable question
“Am I really suited to this job?” is too broad and can easily turn a report into a verdict. You could rewrite it as: “When opinions conflict, how do I usually express disagreement? What do I want to notice at the next review?” The first question demands a definite answer about your fate; the second returns attention to behavior and context.
Before starting, write two columns: what you want this test to help you observe, and what it explicitly cannot decide for you. For example, the first column might say, “In high-pressure meetings, am I more likely to stay silent or interrupt?” The second might say, “This result does not decide whether I am competent for the role, and I will not give it to others for screening.”
This distinction is consistent with basic caution in test use. The ITC Guidelines on Test Use emphasize that test interpretation and use should have evidence relevant to the intended purpose, and should avoid overgeneralizing unmeasured characteristics of a person from a single test. Defining the purpose first establishes the boundaries before you see the score.
When answering: be honest and note the circumstances
First look at the scope of the question. If it asks about everyday tendencies, consider several ordinary, concrete situations rather than focusing only on one particularly successful or distressing experience. If the item specifies a time or context, follow its instructions; if it does not, there is still no need to treat one extreme experience as your whole life.
You do not need to choose answers to obtain an “attractive” result. Descriptions of high and low scores do not form a universal ranking of good and bad. For example, an extraversion score alone cannot determine whether someone is suited to leading a project; discussing project performance still requires attention to task demands, support conditions, and actual behavior.
If you were being rushed, very tired, had just experienced conflict, or were in another unusual state while answering, simply note it. The aim is not to pursue a “perfect score,” but to avoid mistaking a particular moment for a long-term conclusion later.
After reading the report, begin with a “report audit”
The first step in reading a report is to separate what is known, what is unknown, and what is unsuitable for use, rather than interpreting personality immediately. The audit card below does not certify any tool; it only helps you see gaps in the information.
| Item to check | Explanation to look for | What to do if it is missing |
|---|---|---|
| Tool and version | Whether the specific instrument or version is identified | Mark “needs verification”; do not directly convert scores from other reports |
| Score type | Raw scores, transformed scores, percentiles, or another scale | Do not treat the number as a universal judgment of high or low |
| Basis for comparison | Whether the comparison group, time, or applicable scope is explained | Do not infer “how many people I exceed” or what level you occupy |
| Answering circumstances | Whether you were rushed, tired, or experiencing a particular event | List the circumstances as a limitation on interpretation |
| Purpose this time | Personal reflection, or something affecting other people's rights and interests | For high-impact uses such as hiring, admissions, or healthcare, do not let this report decide on its own |
The ITC guidelines state that score interpretation requires attention to scales, comparison groups, technical limitations, and testing circumstances, while avoiding overgeneralization. The Standards for Educational and Psychological Testing from AERA, APA, and NCME distinguish two different interpretations: describing current characteristics and predicting future outcomes. Each requires evidence for its intended use. Therefore, “the report seems to describe one of my tendencies” cannot automatically become “the report can predict whether I will succeed.”
The audit card can also tell you when to stop first. For example, if a report shows a percentile without identifying the comparison group or explaining where the score comes from, you can acknowledge that the label resonates with you, but should not treat it as a precise ranking. Even when more explanation is available, still ask whether the supported use matches the problem you now want to address. A complete layout does not automatically turn a general self-description into a judgment of job performance, intimate relationships, or health.
For Xiaolin, a more careful sentence might be: “This report reminds me to observe how I participate in meetings; but I still do not know the basis for comparing 42, and I cannot use it to decide whether I am suited to leading a project.” That is already enough to begin reflection or a conversation.
During the audit, you do not need to fill every blank with a conclusion. You can write three labels beside the report: “explained,” “needs verification,” and “not used this time.” For example, if the tool's name is given, put it in the first category; if the comparison group is unspecified, put it in the second; if you are considering using the result to evaluate someone else, put it in the third for now. The value is not in making the report more authoritative, but in preventing an incomplete number from exceeding the scope it can support.
If more explanation becomes available later, you still do not need to combine everything into one overall judgment. First ask which specific gap the new information addresses: does it explain the score scale, the basis for comparison, or the uses it can support? Each addition updates conclusions only within the corresponding scope. Maintaining this habit of updating one item at a time helps keep your judgment clearer than using a broad “valid” or “useless” when information is insufficient.
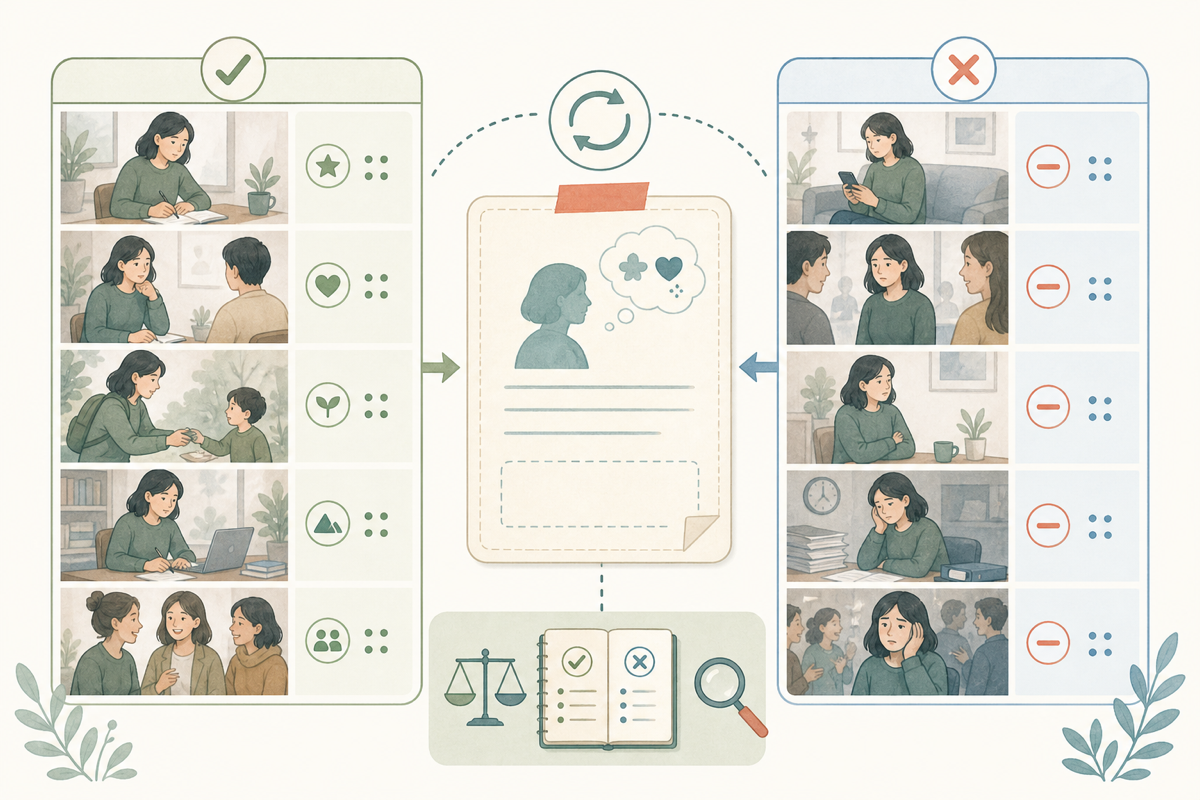
Turn a label into seven days of observation, rather than a personality verdict
Suppose the report describes Xiaolin as “relatively low in extraversion.” She does not need to withdraw from consideration as a project meeting facilitator. She can first choose a narrower question: “In project meetings where I have a relevant question and a chance to speak, do I usually leave that question unasked?”
The following fictional records concern the same behavior. They do not establish a trait level.
| Occasion | Observation | What remains uncertain |
|---|---|---|
| Monday | She had a relevant question and a chance to speak, but did not ask it | She did not record her reason, preparation or time pressure |
| Wednesday | She had a relevant question and a chance to speak, and asked it | This is a contrasting occasion; it does not prove a general pattern |
| Friday | There was no opportunity to speak before the meeting ended | This cannot count as choosing silence or as a counterexample |
After seven days, she can review the record without deciding “I am an introvert.” Seven days is an optional schedule, not a validated duration. If she has not found an exception, she should distinguish that from having enough comparable opportunities and observing none. With few opportunities or missing context, keep the question unresolved. If comparable records repeatedly do not fit, revise or set aside the proposed pattern.
She could later try preparing one question in advance or requesting a speaking turn. Those are changed conditions to record separately, not natural counterexamples to the original situation. Note whether the arrangement was useful, its cost, and what else changed. Better participation alongside a new arrangement does not prove that it caused the change, or reveal which factor caused the original silence. Stop or adjust the trial if it adds burden.
This exercise treats a report as a prompt for observation. It does not validate the report or determine leadership ability. Preparation, topic familiarity, workload and team structure remain questions to investigate rather than explanations already established.
Sharing the Big Five framework does not make tools interchangeable
Tools may differ in their number of items, level of detail, scoring, testing context, and disclosure. Soto and John's (2017) research on the BFI-2 provides a specific example: the full version in that series has 60 items, with a 30-item short form and a 15-item extra-short form; within the scope of that study, the 15-item BFI-2-XS should not be used for facet traits.
This example only shows that different designs and interpretation boundaries can exist within the same framework. It cannot be generalized to all short tests, and cannot establish that “more questions mean greater accuracy,” that paid tools are necessarily better than free tools, or that reports without disclosed technical materials have a particular quality.
When choosing or using a tool, first check whether it explains its purpose, version, method of score interpretation, and whether it provides technical materials that can be examined. If information is insufficient, you do not need to rush to label the tool “invalid”; a more reasonable approach is to narrow its use to personal reflection, rather than using it for screening, diagnosis, hiring, educational progression, or financial or legal decisions.
Do not let a report replace a real conversation
“Low agreeableness” is unsuitable as a direct explanation of a colleague. If you want to improve a disagreement, you can turn the label into something discussable: “I tend to point out risks first, but I do not want to skip over your proposal. Could we each start by stating one concern and one condition that would make it workable?” This leaves more room for dialogue than “That is just my personality.”
Similarly, when someone does not want to share their result, respecting the refusal matters more than asking for the score. Test results should not become a shortcut for labeling partners, colleagues, or job applicants. If a problem requires professional judgment, or is already noticeably affecting everyday life and safety, online personality content cannot replace the appropriate professional support.
FermatMind: disclosed methods and remaining evidence gaps
The FermatMind Big Five landing page describes its shorter 90-item form and its 120-item adaptation of the IPIP-NEO-120 structure. It discloses five domains and a 30-facet framework, and parts of the scoring method: reverse coding of a 1–5 response as y = 6 − x, mean scores, and z/T transformations. This is partial method disclosure, not the complete item-to-score key or evidence of product validity. With usable reference parameters, the percentile is an estimate from a normal model. Without usable norms, the linear 0–100 score expresses position on the score scale. Product-specific reliability, validity, representative norms, sample composition, measurement error, language equivalence, meaningful change, intervention effects, individual prediction, and career or relationship matching remain Unknown where supporting evidence is not disclosed.
Before comparing two reports, record the form, locale and date. Read the five domains first, then any facets actually shown; look for one concrete example and one counterexample. A difference between reports can reflect form, context or response changes, and does not establish improvement. If you need evidence for a specific decision, check whether a study used that exact product, version, population and purpose rather than borrowing a coefficient from a different Big Five tool.
How to read the five dimensions
| Dimension | What to observe first | What not to infer directly |
|---|---|---|
| Openness | Interest in new ideas, change, and complex information | Creativity, intelligence, or career fit |
| Conscientiousness | Habits of planning, sustained effort, and completing tasks | Moral character, ability, or inevitable performance |
| Extraversion | Preferences for social stimulation, expression, and activity levels | Social ability, leadership, or popularity |
| Agreeableness | Cooperation, trust, empathy, and handling conflict | Goodness or badness, obedience, or team value |
| Negative emotionality | Sensitivity to stress, worry, and clues about recovery | Psychological diagnosis, fragility, or future health |
High and low scores are not universally better or worse. Choose a real situation and record supporting evidence, counterexamples, and environmental conditions together; if the report does not explain the instrument, score type, or comparison group, first mark “needs verification.”
For a refresher on the five letters, see what OCEAN means. If your report uses score bands, the guide to high, middle, and low Big Five scores explains how to read them in context.
Frequently asked questions
What should I look at first in Big Five results?
First look at the tool and version, the names of the five dimensions, the score type, and the basis for comparison, then examine the high or low position of each dimension. Without a scale, norms, or reference group, do not interpret a number directly as a ranking, a judgment of good or bad, or a measure of ability.
Do high and low scores on the five Big Five dimensions mean good and bad?
They do not mean universally good or bad. Openness, conscientiousness, extraversion, agreeableness, and negative emotionality are continuous dimensions; the same tendency may bring different advantages and costs across tasks, relationships, and stressful environments.
Should two dimensions be considered together?
You can observe several dimensions in the same situation, but should not use them to invent fixed personality types. For example, meeting participation may be affected by extraversion, stress, preparation time, and team structure together; a combined interpretation must still preserve context and counterexamples.
What if Big Five results differ or change on retesting?
First check whether the tool, version, scoring method, and comparison group are the same, then record fatigue, stress, and recent events when answering. Differences may reflect the tools, context, or real change; when information is insufficient, mark “needs verification.”
Can Big Five results be used for hiring, diagnosis, or career prediction?
This article does not support these uses. A single online result cannot independently be used for applicant screening, medical or psychological diagnosis, assessment of ability, admissions, career fit, or predicting success; high-impact decisions require independent evidence and professional processes matched to the intended use.
Next step
If you want to turn this reading into structured self-observation, you can start the Big Five personality test. Use the results only to propose testable hypotheses, rather than replacing judgments about ability, hiring, diagnosis, or the future.
References and next steps
- Goldberg, L. R. (1990). *An alternative “description of personality”: The Big-Five factor structure*. Journal of Personality and Social Psychology, 59(6), 1216–1229. DOI: 10.1037/0022-3514.59.6.1216. This article uses it only to explain the scope of research on the five-factor structure.
- Soto, C. J., & John, O. P. (2017). *Short and extra-short forms of the Big Five Inventory–2: The BFI-2-S and BFI-2-XS*. Journal of Research in Personality, 68, 69–81. DOI: 10.1016/j.jrp.2017.02.004. This article uses it only to explain the trade-offs in short forms of that particular BFI-2 series.
- International Test Commission. (2013). *ITC Guidelines on Test Use*.
- American Educational Research Association, American Psychological Association, & National Council on Measurement in Education. (2014). *Standards for Educational and Psychological Testing*.
The next time you open a Big Five report, first use the audit card to establish what the number actually explains and what is still missing, then decide whether a small round of observation is worthwhile. If information is still insufficient, not using the score for now is more careful than rushing to find a more emphatic explanation.

